
Project "Database of Ukrainian dialects"
Description
The database is under development and currently has over 110.000 datapoints (primarily phonetics) from over 900 locations in Ukraine supplied with GPS. In collaboration with the Institute of the Ukrainian language (Kyiv). Currently funded by the Chair of Slavic Linguistics and the Network for Digital Humanities of U Potsdam
Report: Preparatory Digitization of the Atlas of the Ukrainian Language (AUM)
Status: 26 August 2026
The preparatory phase has focused on securing and structuring core materials from the Atlas of the Ukrainian Language (AUM) held at the Institute of Ukrainian Language in Kyiv. This work directly supports the objective of preserving Ukrainian dialectal heritage and integrating it into a sustainable, searchable digital infrastructure organized around approximately 2,300 surveyed localities.
1. Securing the archival sources
Two colleagues in Kyiv, Oleksandr Ishchenko and Liudmyla Koliesnyk, have been scanned the handwritten AUM materials in a controlled workflow with review, transfer to the shared archive, and an additional local backup. The archive comprises about 2,500 settlement folders containing handwritten A5 notebooks; these materials require manual scanning. The approximately 3 million index cards underlying the AUM are planned for separate sheet-fed digitization.
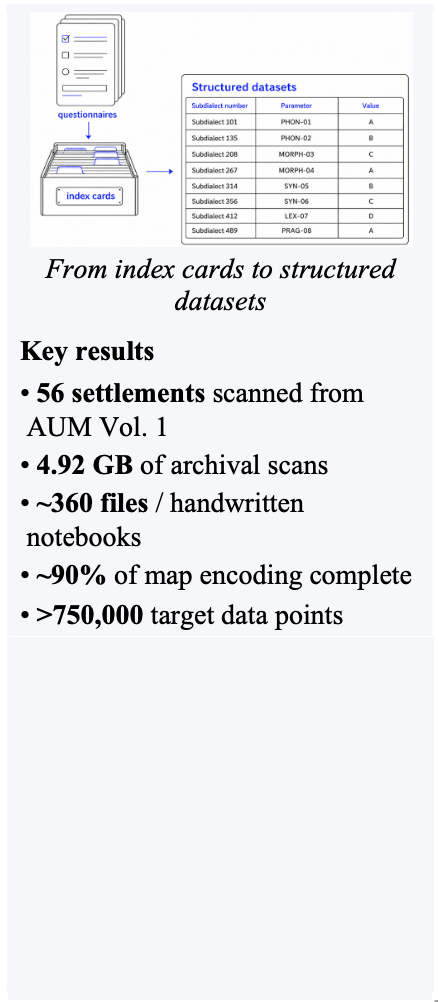
By 26 August 2026, scans had been completed for 56 settlements from AUM Volume 1, amounting to 4.92 GB and roughly 360 files.
2. Converting the printed AUM into structured data
Building on the map-to-data workflow established in the preparatory work, the current goal is to digitize all three AUM volumes: about 1,250 maps covering approximately 2,300 geographical points and more than 750,000 individual data points. All place names and related geographic information have already been entered. Encoding of graphical map information is about 90% complete: Volume 1 is complete, while approximately 620 of 690 maps in Volumes 2 and 3 have been encoded.
In parallel, map titles and linguistic layers are being systematically reviewed, including English title translations and map vocabulary. Documentation of the conversion process is under way, and consolidation into the final dataset has started. The remaining major tasks are to complete map encoding and review, finalize documentation and dataset integration, and develop the user-facing search, filtering, viewing, and download interface.
Overall, the preparatory work has established both a reliable preservation workflow for vulnerable primary sources and a mature pipeline for transforming the published atlas into reusable research data. These results provide a concrete technical and empirical foundation for the larger infrastructure and its future research applications.